Company Knowledge Base: Plain-Language Search across 23,620 Documents
Why Standard Cloud Stacks and Legacy Tools Failed
Years of tenders, technical sheets, certificates, contracts and correspondence were spread over shared drives in dozens of formats. Finding the right document meant knowing who had saved it and under what name.
Custom Low-Latency Architecture & In-Country Execution
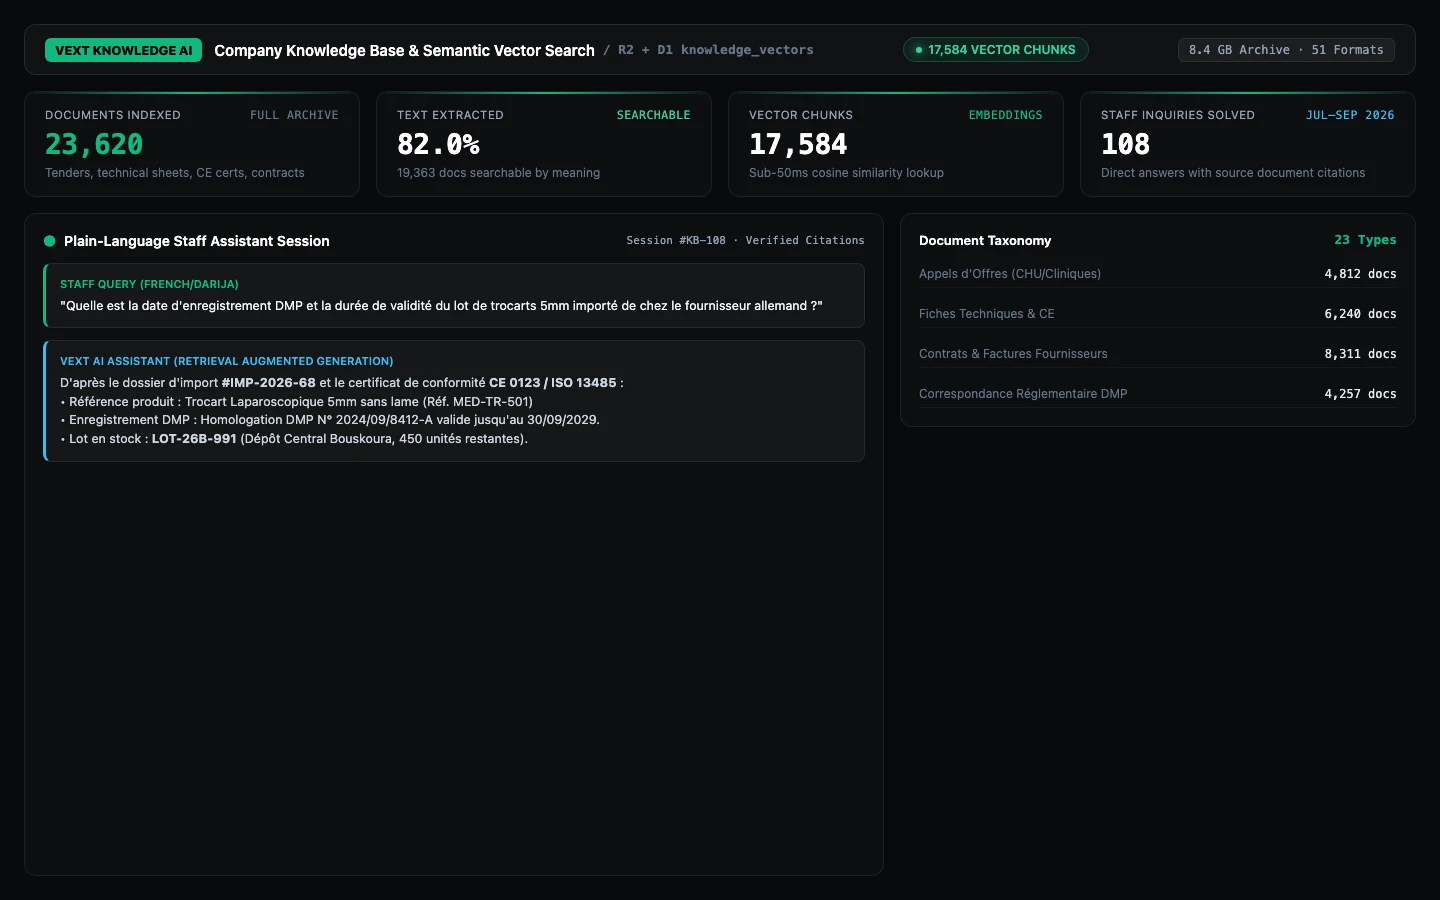
Vext indexed the document archive, classified each file into one of 23 document types, extracted its text and split it into chunks with embeddings. Staff ask the assistant a question; it retrieves the most relevant passages and answers from them, pointing back to the source documents.
Key Engineering Deliverables
- Indexing of the company document archive across 51 file formats
- Classification into 23 document types and text extraction
- Embedding-based semantic search over the extracted text
- Question-answering assistant for staff, with links to source documents
Measured Production Impact
- Text extracted from 19,363 of 23,620 documents (82%), making them searchable by meaning, not file name
- 108 staff questions answered through the assistant between July and September 2026
- One index across 23 document types instead of scattered shared drives
Architectural Context & Deployment Narrative
A distributor accumulates documents faster than anyone can file them. Vext indexed 23,620 of them (8.4 GB in 51 file formats, sorted into 23 document types) and extracted text from 19,363, or 82%. That text was split into 17,584 embedding chunks so the archive can be searched by meaning. Staff now ask the assistant questions in plain language; between July and September 2026 it answered 108 of them, each answer drawn from the company’s own documents.
Have a similar engineering challenge?
Speak directly with the lead systems architect behind this deployment.
More Production Case Studies
Vext Voice: Morocco’s Sovereign Darija & French AI Voice Telephony Engine
Casablanca bare-metal telephony & WhatsApp VoIP gateway executing Moroccan Darija and French conversational agents with sub-400ms voice latency, direct IAM/Orange/Inwi SIP trunks, mid-call GPS & CMI multimodal actions, and 0.34 MAD/min runtime economics under 100% CNDP Law 09-08 compliance.
AI Email Intelligence: From a Distributor’s Inbox to Tracked Obligations
56,457 emails from 22 mailboxes, going back to February 2017, read by an LLM and turned into structured facts (intent, counterparty, amounts, deadlines, urgency), with 7,939 payment, delivery and regulatory obligations extracted and tracked automatically.